At Photoroom, our data stack is built around three tools: Snowflake as our warehouse, dbt to transform the data, and Omni as our BI tool, where people across the company build their own dashboards and query data on their own. We also use Amplitude for product analytics, but it isn't part of this story.
This article is about keeping dbt aware of what happens in Omni. Every night, a job records in dbt which models each piece of Omni content reads from, about 200 of them in total, and we merge one of its pull requests on most working days.
The problem
ℹ In dbt, an exposure is an entry in the project that declares something living outside dbt, like a dashboard, and the models it reads from. dbt uses it to extend the lineage graph all the way to what people actually use.
When we started, dbt had no idea Omni existed: nothing in the repo said which dashboards or topics read from which models. We wanted the full picture somewhere, from the models all the way to what people actually use, and dbt was where we wanted it.
dbt's exposures feature is built for this. You declare "this model feeds this downstream thing" and it shows up in dbt docs, lineage graph included. The catch is that someone has to write those entries and keep them current. We have about two hundred dashboards and topics, and people create new dashboards every day. We weren't going to write those entries by hand, and even if we had, nobody would have kept up for long.
So we automated it. Every night, a GitHub Action generates the exposures for both dashboards and topics, and opens a pull request if anything changed. Once the CI passes, a Slack message lets the team know, and someone reviews the PR and merges it.
Two methodologies, because Omni's API only covers half the problem
We track both dashboards and topics on purpose.
ℹ In Omni, a topic is the semantic-layer object people query against: a base view plus its joins, roughly the equivalent of a dbt semantic model. At Photoroom, we keep it simple: each topic is built on one base view, which maps to one table and one dbt model, and we add joins only when a topic really needs them.
We believe in self-serve (more on that in AI for BI: write definitions as code): our end users query topics directly and build their own dashboards. A topic that returns inconsistent numbers worries us even more than a broken dashboard: a broken dashboard is obvious, while a wrong number can go unnoticed for weeks. Both belong in the lineage.
Each one comes from a different source:
Dashboards: Omni's
dbt-exposuresAPITopics: the semantic-layer files in the GitHub repo Omni is connected to
Dashboards: pulled from Omni's API
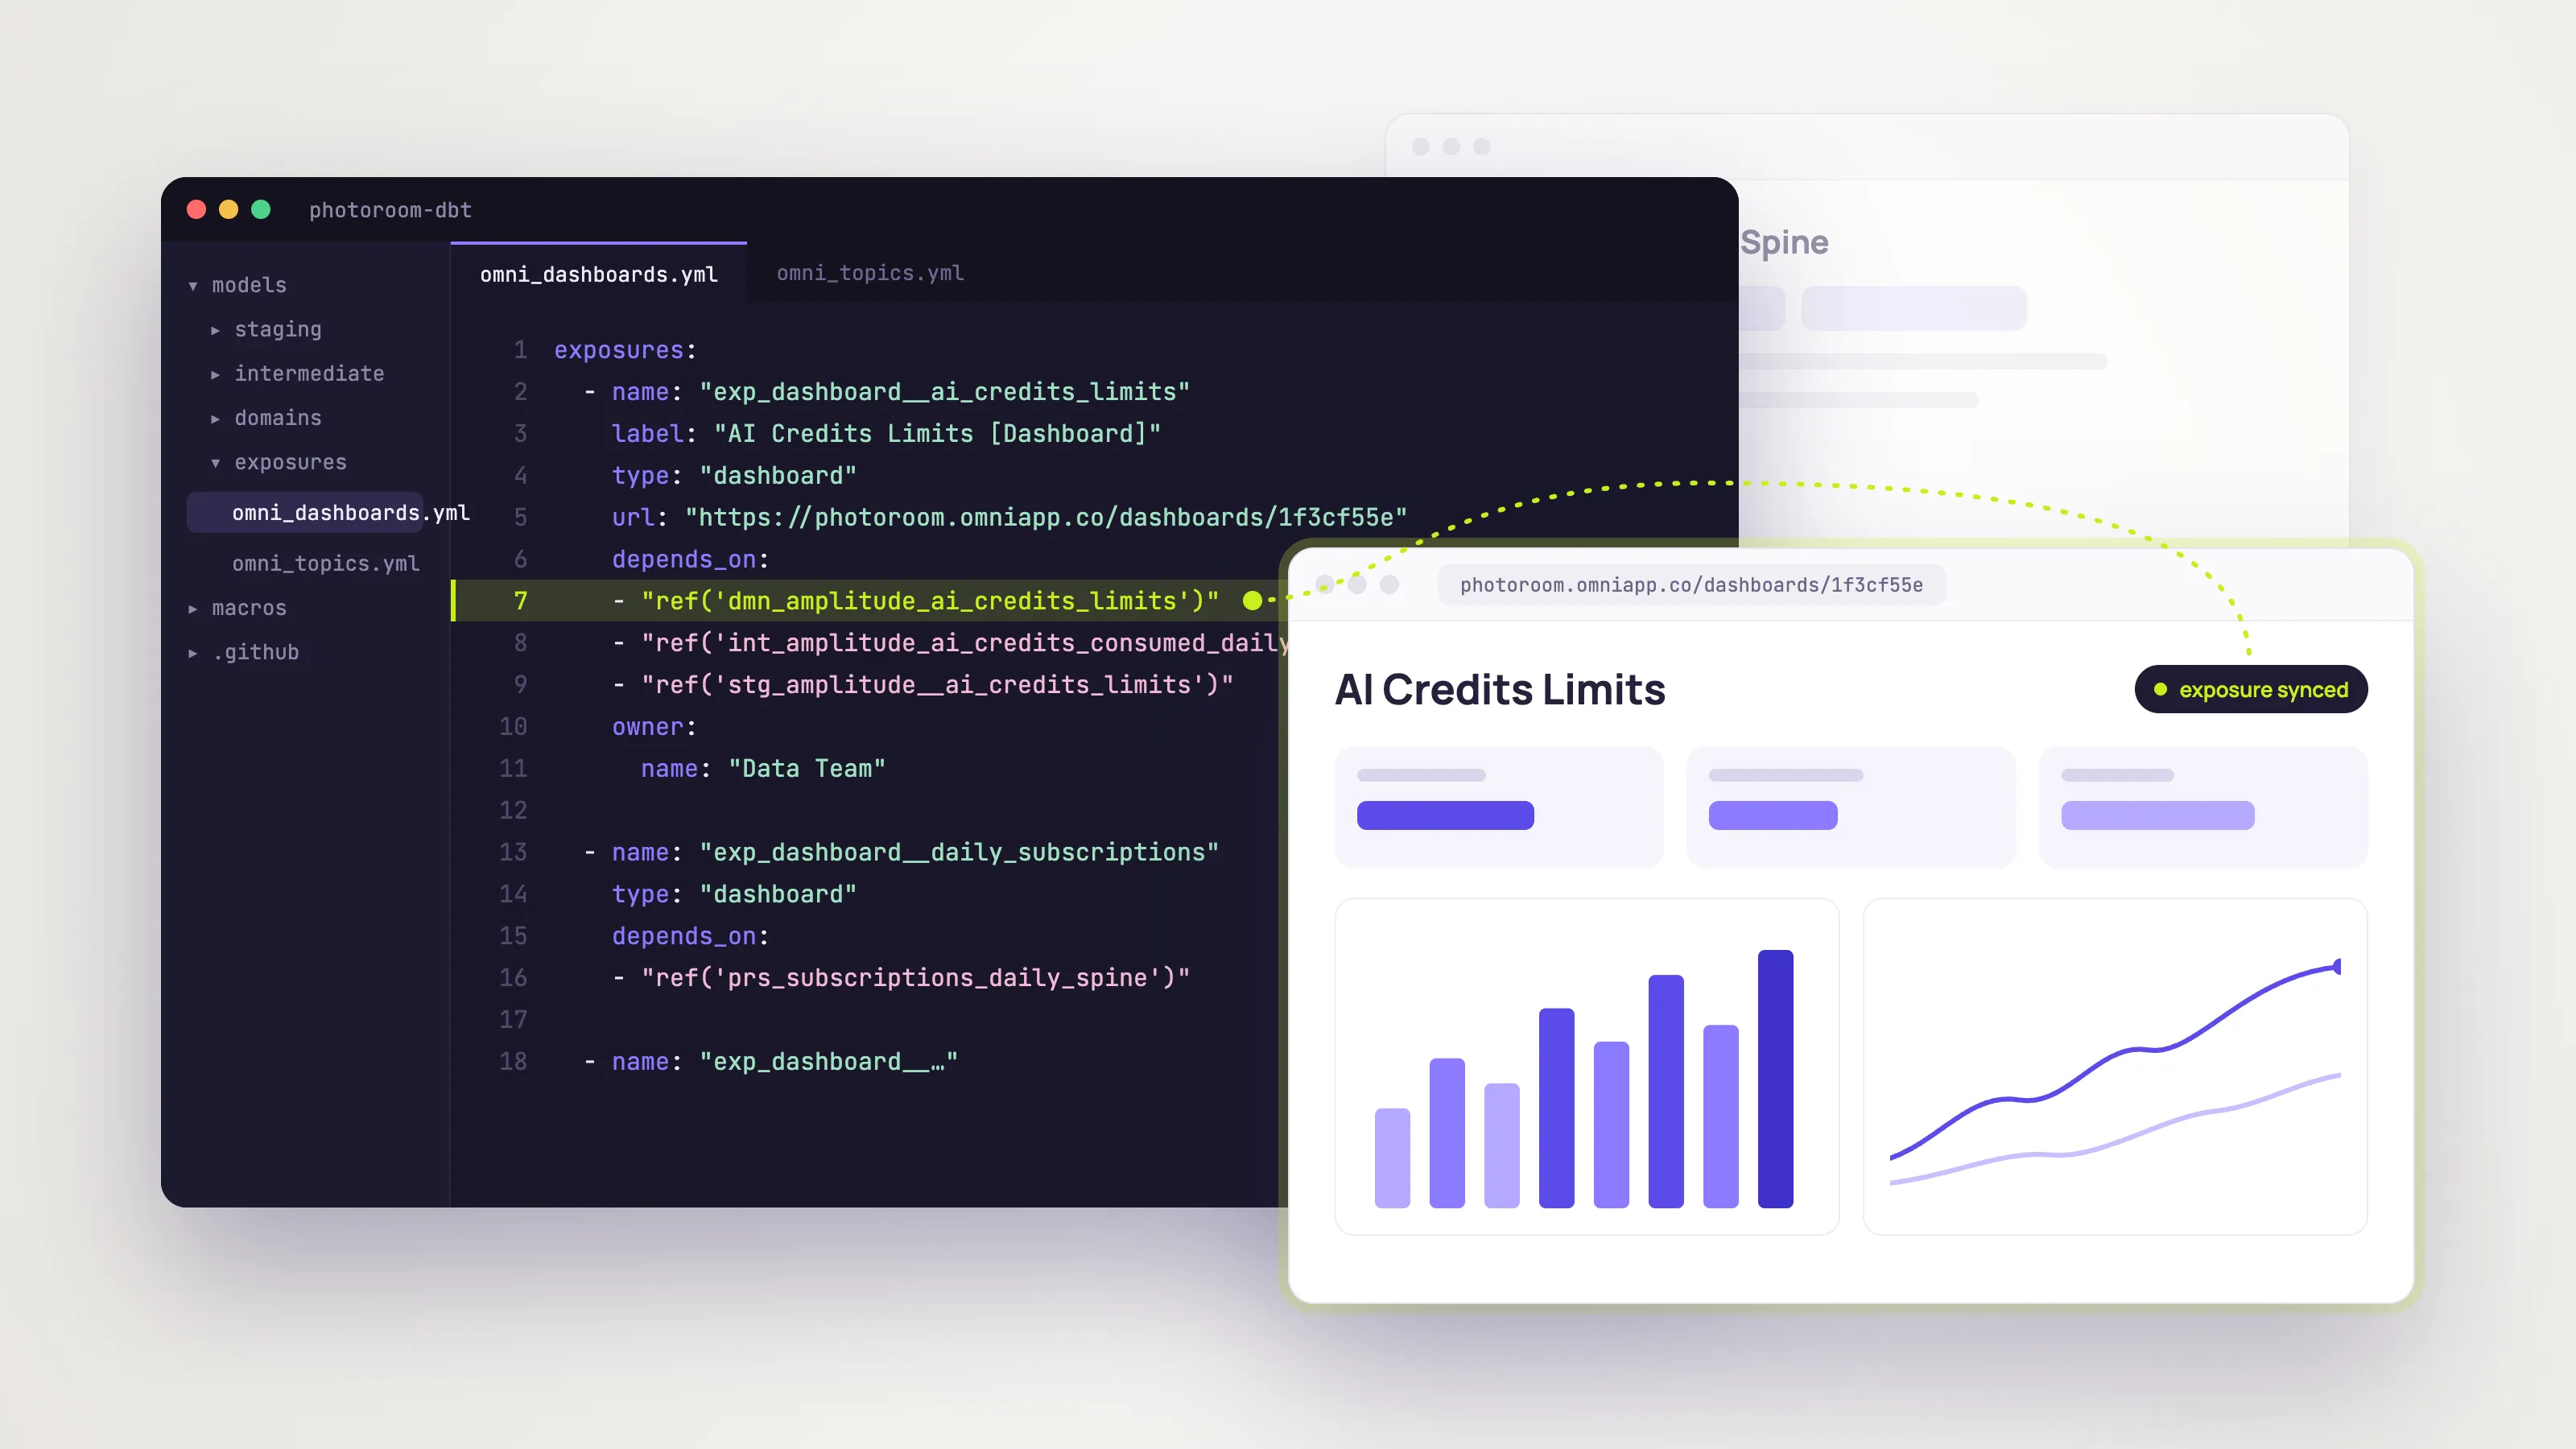
Omni exposes a dbt-exposures REST API endpoint per model that returns every dashboard and what it queries. A script calls it and writes the result to an exposures YAML file in our dbt project. The depends_on property on each exposure is what tells us which dashboard depends on which dbt model. Right now that file tracks 101 dashboards. One entry looks like this:
- name: "exp_dashboard__ai_credits_limits"
  label: "AI Credits Limits [Dashboard]"
  type: "dashboard"
  url: "<https://photoroom.omniapp.co/dashboards/1f3cf55e>"
  depends_on:
  - "ref('dmn_amplitude_ai_credits_limits')"
  - "ref('int_amplitude_ai_credits_consumed_daily')"
  - "ref('stg_amplitude__ai_credits_limits')"
  owner:
    name: "<dashboard owner>"
    email: "<owner email>"
The generator deliberately mirrors the format Omni's own "push to dbt" button produces, so a diff against a manually pushed file stays clean instead of turning into a wall of formatting noise.
Topics: read from Omni's GitHub repo
Omni's dbt-exposures API doesn't return topics at all, only dashboards. So instead of an API call, we read the repo Omni is connected to. Through its GitHub integration, Omni keeps our whole semantic layer as YAML in a private repo, updated in real time, with one file per topic and one per view. That's where the topic generator gets its input.
Each topic file declares a base_view and its joins, each view file carries a schema and table_name. Where that table lives in our DBT_PROD schema, we can resolve it straight to a ref(). Where it doesn't (a raw source, an uploaded CSV), we drop it and log the skip. This currently produces 97 topic exposures:
- name: "exp_topic__daily_subscriptions_spine_last_60d"
  label: "Daily Subscriptions Spine Last 60d [Topic]"
  type: "application"
  description: "Model created based on prs_subscriptions_daily_spine for the past 60 days..."
  depends_on:
  - "ref('dmn_integrations_users')"
  - "ref('prs_subscriptions_daily_spine')"
  owner:
    name: "Data Team"
dbt has no notion of a topic. Exposures come with a fixed list of types (dashboard, notebook, analysis, ml, application), and none of them fits a semantic-layer object. We went with application, the closest match.
Naming convention
dbt requires exposure names to be unique, lowercase snake_case, and raw Omni names didn't always follow that. So both generators build names the same way, from the exposure's label: exp_dashboard__<name> or exp_topic__<name>, with _2, _3 appended when two names collide.
Every label also ends with [Dashboard] or [Topic]. For topics, that makes up for the application type, which can't say "topic" on its own: anyone browsing dbt docs can tell at a glance what kind of Omni object they're looking at.
One GitHub Action, one persistent PR
The nightly run
Both generators run from the same nightly GitHub Action, which:
Calls the Omni API for dashboards.
Fetches the topic definitions from the repo Omni is connected to.
Runs both generators, the dashboard one and the topic one.
Diffs the result against what's committed. No diff, no further action.
If there's a diff, force-pushes to the same branch every time instead of creating a new one. While the PR is open, it just gets updated; once it's merged, the next change opens a fresh PR from that same branch. So there's never more than one sync PR waiting, and if nobody merges for a few days, that PR carries the latest full state instead of three stale ones conflicting with each other.
Bots propose, humans approve
It's our motto in the data team, until it isn't anymore. The workflow opens the pull request, but it never merges it: someone on the team reads the diff and decides. It's the same rule Juliette applied when she used agents to fill 1,500 missing Amplitude definitions: the agent proposes, only a human applies.
For this sync, though, the human doesn't add much. The PR only catches dbt up with what already exists in Omni, so there's nothing to judge, just something to acknowledge. We keep a human in the loop anyway, on principle: we're not ready to let agents merge on their own yet. That's the part we expect to change.
In practice, we merged a sync PR on 20 of the last 26 working days, usually first thing in the morning, each one a small, reviewable diff instead of a slow accumulation of drift.
So what
A truthful lineage graph is a nice property to have, but let's be honest: almost nobody opens dbt docs to look at it. It sits there, correct, mostly unvisited. The real payoff isn't the graph itself, it's what you can build on top of it once you trust it.
The existing PR-bot pattern
We already have a similar pattern elsewhere in the same PR flow. On every pull request, three bots comment automatically:
A metric delta bot that compares revenue figures between production and the CI build of any changed reporting model, period by period, so a reviewer sees the actual data impact of a change, not just the SQL diff.
A cost impact bot that speaks up when a changed table's size differs from production (more or fewer rows or columns), and estimates how the daily Snowflake cost changes.
A reminders bot that looks at which files changed and tells a maintainer what manual step to take after merge, like applying an infrastructure change or fully rebuilding a model whose columns changed.
None of them act. They all stop at telling a human what to look at, which is the same bots-propose-humans-approve shape as the exposure sync.
The next step: an exposure-aware impact flag
The exposure files we now have are the missing ingredient for one more check in that list: a PR that changes a model could look it up in the two exposure files, find every dashboard and topic that depends on it, and post exactly that: "this touches 3 dashboards and 1 topic, here they are, go take a look." Today that lookup is possible by hand and isn't automated. It's the obvious next step once you already have the exposure data sitting in the repo. And the one after that is just as predictable: letting the bot propose the fix too, not just point at the problem.
The use case we're most excited about: warning people right where they look
Say a model stops refreshing overnight and its data goes stale, which is by far the most common problem we run into. The exposure files let us walk the lineage downstream and find every dashboard built on that model. From there, we could automatically add a short warning at the top of each of those dashboards: "This data hasn't been refreshed since Tuesday. We're on it." Once the model is back to normal, the warning disappears. Omni's API already allows it: a script can add a text tile to an existing dashboard and publish it.
We prefer this to pinging every owner on Slack. A Slack message reaches people who may not open the dashboard that day, and with enough dashboards it quickly becomes noise. A warning on the dashboard itself only reaches the people actually looking at the numbers, at the moment they look at them.
This is where exposures pay off the most. Without lineage, the people who rely on bad data are usually the last to know: they spot a number that looks wrong in a meeting, or never notice at all. With it, the warning is there before they read a single number, along with the news that someone is already fixing it. That's how you build trust in data, especially in a team that believes in self-service.
It keeps the same shape as everything else here: the bot informs, a human decides what to do. And bots are already part of how we run data quality, like the Slack one that checks every new Amplitude event name before it gets created.
What this doesn't solve
In an ideal world, we would make a change in dbt and Omni would adapt on its own. We're not there yet. When a dbt model changes, updating the topics that rely on it is still a manual step in Omni. We think our automations will get there soon, but for now, a human does it.
Conclusion
Nothing here is specific to Photoroom. If your BI tool can tell you what each dashboard reads, through an API or a repo, you can generate dbt exposures the same way: run it every night, keep one pull request open, and start with a human merging it. Once the diffs prove boring, the only question left is whether you're comfortable letting an agent merge on its own. Once the lineage stays accurate on its own, you can start building on top of it, from impact checks on pull requests to early warnings on the dashboards themselves.